Human-in-the-Loop AI Agents: Approvals That Earn Autonomy
In my own agent work I have caught myself doing something I do not like. The agent asks permission to run a tool, and I approve. It asks again, I approve again. After enough of them I am approving without reading, because the ones before were fine. That is the weakness of every human-in-the-loop checkpoint: repeat it often enough and it decays into a rubber stamp.
While building this post I tested how bad that gets. With part 2's operator role and its 14 tools, I asked llama3.1:8b to save a copy of the supplier contract and approved every proposal without reading it. Four runs proposed a copy holding the text of a tool call, read_text_file(path='supplier-contract.txt'), or just open, where the contract should have been. The fifth never asked. I approved, and the copy held that one line and none of the contract. In an earlier round on a 3B model, the agent proposed overwriting the contract itself. I approved that too, and lost the contract until I restored it from a backup. The checkpoint was there. Nobody was looking.
In part 2 we built a gate that decides what an agent may touch, and part 3 added checks on the tools and the answers. That was the Foundation. This post builds the second tier, Workflow: a human checkpoint on the calls that matter, a tally of every decision, and a rule that removes the checkpoint once the evidence allows it and brings it back when the model changes.
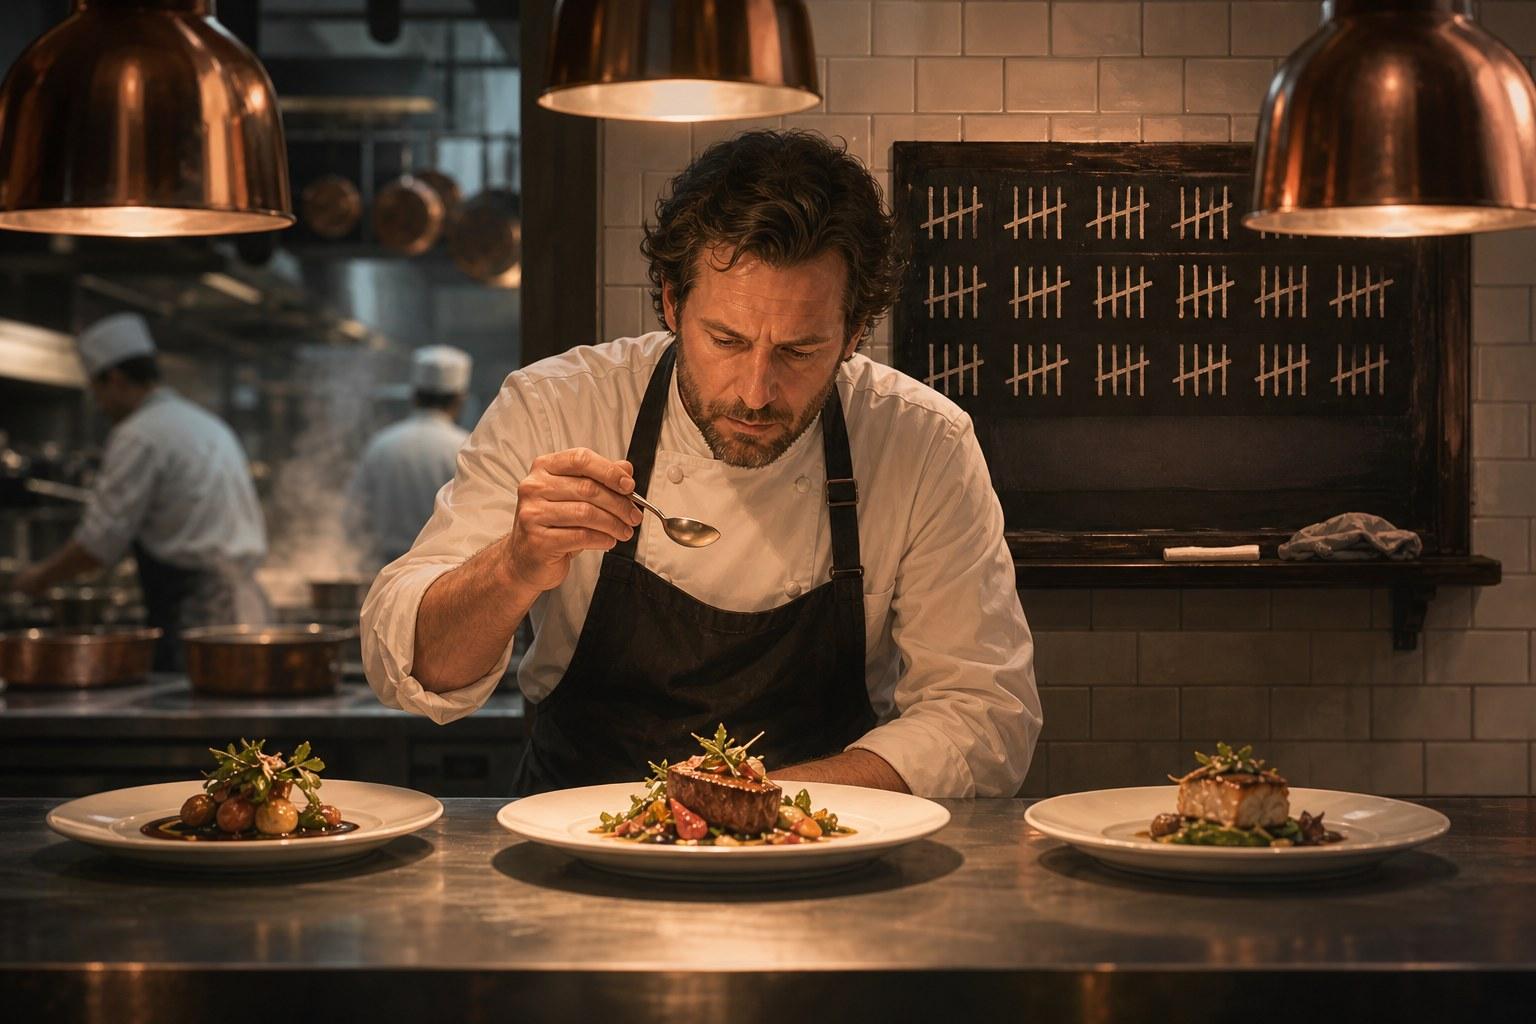
The Tasting Spoon at the Counter
Back in the same kitchen. At the counter where food leaves the kitchen, the head chef tastes each dish with a spoon and sends it out or sends it back, sometimes with a note: less salt, make it again. Cold starters go straight out untasted. A list on the wall says which dishes get tasted, and the cooks cannot edit it.
Next to the counter hangs a tally board, with the current menu at the top and one row per cook per recipe, and a mark for every dish sent out or sent back. After N dishes in a row with nothing sent back, that dish comes off the tasting list. A new menu wipes the board and puts every dish back on the list. And when a guest gets sick, the dish goes back on the list, whatever the board said.
Part 3's second chef, holding each plate against the recipe card, is the automated judge. This head chef is a person, tasting for trust.
The checkpoint stops a bad tool call, and the decision log decides when the checkpoint can come off.
The kitchen breaks in three places. A cook keeps their skill under a new menu, while an agent on a new model really is a different cook, so here a fingerprint wipes the board automatically. Tasting is cheap for a chef, and reading a proposed file write properly is not, which is where approval fatigue comes from. And the kitchen waits while the chef tastes: my console prompt blocks the whole process, where a durable engine would hang a ticket on the rail and let the cooks keep working.
Human-in-the-Loop Checkpoints That Earn Their Way Out
Anthropic defines workflows as "systems where LLMs and tools are orchestrated through predefined code paths" (Building effective agents). The Workflow tier puts mandatory checkpoints on those paths, and two choices decide whether anyone keeps reading: where the checkpoints sit, and how they come off.
Gate the Risky Tool Calls
Microsoft's Architecture Center puts the first choice plainly: "You can also scope HITL gates to specific tool invocations rather than full agent outputs so that the orchestration can proceed autonomously for low-risk actions." Reading a file runs alone, writing one waits for a person, and any tool the policy does not mention waits too. With the operator token, that safe default put 12 tools behind the checkpoint.
Part 2's rule still holds: no policy in the agent. The agent reads approval-policy.json and never decides what is in it. The file belongs to the business owner of the use case, because they carry the impact when a write goes wrong, and it changes only through a reviewed change, a pull request or a config portal.
Count Overrides Per Model and Prompt
An override is any decision that changes what the agent proposed, a rejection or an edit. A tool is promoted when its last N decisions are clean. My first rule was zero overrides ever, and with a flaky model one early mistake would have blocked promotion forever.
N depends on business impact. A low-impact tool might earn its way out after a handful of decisions, and a high-impact one may never run fully alone. Under my first system prompt, write_file collected 5 decisions with 2 overridden, 40%. With N=3 it stayed under approval. With N=1 the same record would have promoted it, so N is the business owner's dial.
Trust belongs to a model and a prompt, so every decision carries a fingerprint of both. Change either and the evidence starts again, though for a minor change the business owner may set a smaller N. Incidents go into the same log, and one incident restarts the count, like a new model does.
I found out how much that fingerprint depends on its input. My whole first round of tests ran on the 3B llama3.2, because part 2's config pinned the model at the gateway, while the agent's fingerprint said llama3.1:8b. The gateway knew: all 81 requests in that round show gen_ai.response.model=llama3.2 in its access log. A fingerprint is only as honest as its input. In production, build it from the model the gateway reports it served. What the agent asked for is only a request.
| Event | What happens to the tool | Who decides |
|---|---|---|
| Last N decisions clean | Promoted to auto:<fingerprint>, runs alone |
Business owner sets N |
| Reject or edit | Counts as an override, the clean run starts again | The reviewer |
| New model or changed system prompt | New fingerprint, back under approval automatically | Nobody has to remember |
| Minor model or prompt change | Back under approval, may earn it back with a smaller N | Business owner |
| Incident | Count restarts from zero | Whoever records the incident |
Fewer Tools, Better Proposals
A checkpoint only helps if the agent proposes something worth reviewing. With 14 tools, the 3B model often wrote its tool call as broken JSON in the reply text, such as {"name":"write_file","parameters{:":"status.txt", ...}, so nothing reached the checkpoint: one approval request in eight runs. With an editor role of three tools, read, list and write, it made a proper call four times out of four.
The 8B model made proper calls with 14 tools and with 3, and then put the file in the wrong place. With 14 tools the path was right in two of four runs. With 3 tools it was right in one of four, with proposals like /status.txt and /path/to/status.txt. Fewer tools still paid off, cutting input tokens from about 1,690 to 500 per call. The paths needed a clearer system prompt: "Use plain file names such as status.txt, never a path." With that line, six of six runs used the right path.
That fix came with a cost, and it is the right one. The new prompt changed the fingerprint from llama3.1:8b:0c1830c849ec to llama3.1:8b:bc548905e911, so the evidence the first prompt had collected no longer counted. Trust belongs to a model and a prompt, and here it happened for real.
Building the Checkpoint on Your Laptop
Start from the guardrails folder as part 3 left it, with the gateway running and Ollama serving llama3.1:8b and llama3.2. If you cleaned up, rebuild it first. Approval is built into Microsoft.Extensions.AI, so nothing new gets installed.
Step 1: Give the Agent Only the Tools It Needs
Make three changes to config.yaml: add the editor rule, raise the token budget, and remove the model pin under the Ollama entry, so the model the agent asks for is the model that answers. The budget matters because part 2's 20,000 tokens an hour ran out during my testing, with every operator call carrying 14 tool descriptions, about 1,700 input tokens. The gateway answered 429, the OpenAI client retried quietly, and the agent sat for 400 seconds with no output, looking hung instead of failing. Save, and the gateway reloads.
    mcpAuthorization:
      rules:
      - 'jwt.role == "reader" && mcp.tool.name in ["read_text_file", "list_directory"]'
      - 'jwt.role == "operator"'
      # New in this post: read, list and write, nothing else
      - 'jwt.role == "editor" && mcp.tool.name in ["read_text_file", "list_directory", "write_file"]'
  # ... targets unchanged ...
llm:
  port: 4040
  policies:
    localRateLimit:
    - maxTokens: 200000       # was 20000
      tokensPerFill: 200000   # was 20000
      fillInterval: 1h
      type: tokens
  models:
  - name: "*"
    provider: ollama
    # params and model: llama3.2 removed, so the agent's requested model reaches Ollama
    # part 3's guardrails block stays as it is
Then mint Erik's editor token from guardrails, signed with the keypair part 2 left in jwt. In bash:
# From guardrails; the keypair in jwt/ comes from part 2
S="docker run --rm -i -v $PWD/jwt:/work -w /work smallstep/step-cli:0.31.0 step"
EXP=$(date -d '+30 days' +%s)   # macOS: EXP=$(date -v+30d +%s)
echo '{"role":"editor"}' | $S crypto jwt sign --key priv.json --iss demo.local --aud foundation-demo --sub erik --exp $EXP > jwt/editor.jwt
In PowerShell:
# From guardrails; the keypair in jwt/ comes from part 2
$exp = [DateTimeOffset]::UtcNow.AddDays(30).ToUnixTimeSeconds()
'{"role":"editor"}' | docker run --rm -i -v "${PWD}/jwt:/work" -w /work smallstep/step-cli:0.31.0 step crypto jwt sign --key priv.json --iss demo.local --aud foundation-demo --sub erik --exp $exp | Set-Content jwt/editor.jwt
Step 2: Write the Policy
Save this as approval-policy.json in guardrails. Read tools run alone, and write_file waits for a person. In production the file sits in a repository the business owner controls.
{
  "read_text_file": "auto",
  "list_directory": "auto",
  "write_file": "approve"
}
Step 3: Build the Checkpoint Agent
Create the app inside guardrails with the three packages from part 2's GuardedAgent:
# The same in bash and PowerShell
dotnet new console -n CheckpointAgent
cd CheckpointAgent
dotnet add package Microsoft.Extensions.AI --version 10.11.0
dotnet add package Microsoft.Extensions.AI.OpenAI --version 10.11.0
dotnet add package ModelContextProtocol --version 2.2.0
Replace Program.cs with this:
using System.ClientModel;
using System.Security.Cryptography;
using System.Text;
using System.Text.Json;
using Microsoft.Extensions.AI;
using ModelContextProtocol.Client;
using OpenAI;

var token = File.ReadAllText(args[0]).Trim();
var role = Path.GetFileNameWithoutExtension(args[0]);
var prompt = args[1];
var model = Environment.GetEnvironmentVariable("AGENT_MODEL") ?? "llama3.1:8b";
const string systemPrompt = "You are a document assistant. Use the tools to work with files in the shared folder. Use plain file names such as status.txt, never a path.";

// Trust belongs to a model and a prompt. Change either and the fingerprint changes.
var fingerprint = $"{model}:{Convert.ToHexString(SHA256.HashData(Encoding.UTF8.GetBytes(systemPrompt)))[..12].ToLowerInvariant()}";
Console.WriteLine($"[fingerprint] {fingerprint}");

// Humans own this file. A tool is "auto", "approve", or "auto:<fingerprint>" once promoted.
var policy = JsonSerializer.Deserialize<Dictionary<string, string>>(File.ReadAllText("../approval-policy.json"))!;
bool RunsAlone(string tool) => policy.GetValueOrDefault(tool, "approve") is var mode
    && (mode == "auto" || mode == $"auto:{fingerprint}");

await using var mcp = await McpClient.CreateAsync(new HttpClientTransport(new HttpClientTransportOptions
{
    Endpoint = new Uri("http://localhost:3030/mcp"),
    AdditionalHeaders = new Dictionary<string, string> { ["Authorization"] = $"Bearer {token}" },
}));
var tools = (await mcp.ListToolsAsync())
    .Select(t => RunsAlone(t.Name) ? (AITool)t : new ApprovalRequiredAIFunction(t))
    .ToList();
Console.WriteLine($"[checkpoint] {string.Join(", ", tools.OfType<ApprovalRequiredAIFunction>().Select(t => t.Name))}");

IChatClient chat = new OpenAIClient(
        new ApiKeyCredential("not-used"),
        new OpenAIClientOptions { Endpoint = new Uri("http://localhost:4040/v1") })
    .GetChatClient(model)
    .AsIChatClient()
    .AsBuilder()
    .UseFunctionInvocation()
    .Build();

List<ChatMessage> messages = [new(ChatRole.System, systemPrompt), new(ChatRole.User, prompt)];
var options = new ChatOptions { Tools = tools, AllowMultipleToolCalls = false };

while (true)
{
    var response = await chat.GetResponseAsync(messages, options);
    messages.AddRange(response.Messages);

    var requests = response.Messages.SelectMany(m => m.Contents).OfType<ToolApprovalRequestContent>().ToList();
    if (requests.Count == 0)
    {
        Console.WriteLine(response.Text);
        break;
    }

    foreach (var request in requests)
    {
        var call = (FunctionCallContent)request.ToolCall;
        Console.Write($"[approve?] {call.Name} {JsonSerializer.Serialize(call.Arguments)} (y / n / e <correction>): ");
        var answer = Console.ReadLine()?.Trim() ?? "n";
        var decision = answer == "y" ? "approved" : answer.StartsWith("e ") ? "edited" : "rejected";

        File.AppendAllText("../decisions.jsonl", JsonSerializer.Serialize(new
        {
            at = DateTimeOffset.UtcNow,
            role,
            tool = call.Name,
            decision,
            fingerprint,
        }) + Environment.NewLine);

        List<AIContent> reply = [request.CreateResponse(decision == "approved", decision == "approved" ? null : "Rejected by the reviewer.")];
        // An edit is a rejection plus a new instruction from the reviewer.
        if (decision == "edited") reply.Add(new TextContent($"Try again: {answer[2..]}"));
        messages.Add(new ChatMessage(ChatRole.User, reply));
    }
}
The parts that matter:
- The system prompt carries the plain-file-name line that fixed the paths.
- The fingerprint is the model name plus the first 12 hex characters of a SHA-256 hash of the system prompt.
RunsAlonetreats a tool as safe when the policy saysauto, orauto:with the current fingerprint. Anything else needs approval, including tools the file does not mention.ApprovalRequiredAIFunctionwraps every other tool, so a call comes back as aToolApprovalRequestContentinstead of running.AllowMultipleToolCalls = falsemeans one call per approval.- The loop shows the call with its arguments, writes the decision, role and fingerprint to
decisions.jsonl, and answers throughrequest.CreateResponse. - An edit is a rejection plus a separate instruction,
Try again: <correction>. My first version put the correction in the rejection reason, and in three of three runs the 3B model never retried and answered in text. With the separate instruction, the model retried every time in my runs.
Step 4: Run It and Decide
From CheckpointAgent, ask for a one-line note:
# The same in bash and PowerShell
dotnet run -- ../jwt/editor.jwt "Write a one-line note to status.txt saying: contract review done, no issues found."
# [fingerprint] llama3.1:8b:bc548905e911
# [checkpoint] write_file
# [approve?] write_file {"content":"contract review done, no issues found.","path":"status.txt"} (y / n / e <correction>): y
# <the model's reply, different on every run>
Your hash matches mine only if the system prompt is identical, character for character. Type y and status.txt appears in docs. Type n and nothing is written. Type e and a correction, and the model tries again. Under the first prompt, the model proposed "path":"/status.txt", I answered e use the plain file name status.txt, and it retried with status.txt, which I approved. The log got an edited line followed by an approved one.
Step 5: Measure and Move the Line
Save this as trust.mjs in guardrails. It counts the decisions for one tool and one fingerprint since the last incident, and rewrites that tool's entry in the policy.
// Usage: node trust.mjs check <tool> <fingerprint> <minDecisions>
//        node trust.mjs incident <tool> "<what happened>"
import { appendFileSync, existsSync, readFileSync, writeFileSync } from "node:fs";

const [command, tool, arg, min] = process.argv.slice(2);

if (command === "incident") {
  appendFileSync("decisions.jsonl", JSON.stringify({ at: new Date().toISOString(), tool, incident: arg }) + "\n");
  console.log(`incident recorded for ${tool}: the count starts again`);
} else if (command === "check") {
  const lines = existsSync("decisions.jsonl")
    ? readFileSync("decisions.jsonl", "utf8").trim().split("\n").filter(Boolean).map(JSON.parse)
    : [];
  // Only evidence since the last incident, for this model and prompt, counts.
  const lastIncident = lines.findLastIndex(l => l.tool === tool && l.incident);
  const decisions = lines.slice(lastIncident + 1).filter(l => l.tool === tool && l.fingerprint === arg && l.decision);
  const overrides = decisions.filter(l => l.decision !== "approved").length;
  const rate = decisions.length ? Math.round((100 * overrides) / decisions.length) : 0;
  // Promotion needs the most recent decisions to be clean, not a perfect history.
  const recent = decisions.slice(-Number(min));
  const earned = recent.length === Number(min) && recent.every(l => l.decision === "approved");

  const policy = JSON.parse(readFileSync("approval-policy.json", "utf8"));
  policy[tool] = earned ? `auto:${arg}` : "approve";
  writeFileSync("approval-policy.json", JSON.stringify(policy, null, 2) + "\n");

  console.log(`${tool}: ${decisions.length} decisions, ${overrides} overridden (${rate}%), last ${min} clean: ${earned ? "yes" : "no"} -> ${earned ? "runs alone" : "needs approval"}`);
} else {
  console.error("usage: node trust.mjs check|incident ...");
  process.exitCode = 1;
}
Open a third terminal in guardrails, where trust.mjs lives. Run the agent three times in the second terminal, approve each with y, and check in the third after each run:
# Third terminal, in guardrails (cd .. from CheckpointAgent): empty the log first,
# so your numbers match mine
rm -f decisions.jsonl   # PowerShell: Remove-Item decisions.jsonl -ErrorAction Ignore

# Run 1. Second terminal, in CheckpointAgent; answer y
dotnet run -- ../jwt/editor.jwt "Write a one-line note to status.txt saying: contract review done, no issues found."
# Then in the third terminal, in guardrails
node trust.mjs check write_file llama3.1:8b:bc548905e911 3
# write_file: 1 decisions, 0 overridden (0%), last 3 clean: no -> needs approval

# Run 2. The same two commands again: dotnet run (answer y), then node trust.mjs check
# write_file: 2 decisions, 0 overridden (0%), last 3 clean: no -> needs approval

# Run 3. The same two commands once more
# write_file: 3 decisions, 0 overridden (0%), last 3 clean: yes -> runs alone

# Run 4. Second terminal, dotnet run only: this time it asks nothing
dotnet run -- ../jwt/editor.jwt "Write a one-line note to status.txt saying: contract review done, no issues found."
# [fingerprint] llama3.1:8b:bc548905e911
# [checkpoint]

# All commands are the same in bash and PowerShell, except rm at the top
The policy now says "write_file": "auto:llama3.1:8b:bc548905e911". The fourth run makes exactly one write_file call with no prompt, logged by the gateway under erik, and status.txt holds the note. In production the script would open a pull request for the business owner instead of writing the file itself.
Step 6: Watch It Demote
Switch the model and leave the policy alone. llama3.2 is still on your machine from part 2. Then record an incident.
# Second terminal, in CheckpointAgent
AGENT_MODEL=llama3.2 dotnet run -- ../jwt/editor.jwt "Write a one-line note to status.txt saying: contract review done, no issues found."
# [fingerprint] llama3.2:bc548905e911
# [checkpoint] write_file
# (answer n if it asks)

# Third terminal, in guardrails: a guest got sick (the same in PowerShell)
node trust.mjs incident write_file "status.txt overwritten with the wrong customer"
# incident recorded for write_file: the count starts again
node trust.mjs check write_file llama3.1:8b:bc548905e911 3
# write_file: 0 decisions, 0 overridden (0%), last 3 clean: no -> needs approval
In PowerShell, the second terminal sets the model for the session and clears it afterwards:
# Second terminal, in CheckpointAgent
$env:AGENT_MODEL = "llama3.2"
dotnet run -- ../jwt/editor.jwt "Write a one-line note to status.txt saying: contract review done, no issues found."
# (answer n if it asks)
Remove-Item Env:AGENT_MODEL   # back to llama3.1:8b
This time the gateway log shows gen_ai.response.model=llama3.2, so the model really changed. The next post builds on this setup, including the promoted write_file, so keep it if you follow along. Otherwise, stop the gateway with Ctrl+C and remove everything from the folder that holds guardrails:
docker stop aspire-dashboard
ollama rm llama3.1:8b llama3.2
rm -rf guardrails
docker stop aspire-dashboard
ollama rm llama3.1:8b llama3.2
Remove-Item -Recurse -Force guardrails
Human-in-the-Loop Beyond the Laptop
From here the workstation stops being the point. A console prompt blocks the process, which works while the approver sits at the same screen. Once the request goes to email or Teams, or waits until the next morning, the run has to survive restarts. Microsoft's advice is to "persist state at these checkpoints to resume operation without a replay of prior agent work", which is a job for a durable engine: Microsoft Agent Framework workflows, with human-in-the-loop requests and checkpoints, or Temporal. Agent Framework also offers standing "always approve" rules, and its docs warn that they persist and need a new review when the agent or its tools change. That is the fingerprint, left to someone's memory.
The override rate here is a small script over a JSON lines file. At scale, Langfuse scores do the same job, although it is heavy to self-host.
Approval fatigue is a design problem, so fix it in the design. Keep the checkpoint on a few risky calls, show the arguments clearly enough to read, and promote what earns it, because a checkpoint that never comes off teaches people to stop reading. That is what the tally is for.
Taste Until the Tally Says Stop
- Put the checkpoint on the risky calls. Read tools run alone, and unknown tools wait.
- Keep the policy with the business owner. The agent reads it, and every change is reviewed.
- Count rejects and edits as overrides. Promote on the last N clean decisions, with N set by business impact.
- Tie trust to the model that was served and the prompt. A new fingerprint brings the checkpoint back without anyone remembering to, as long as its input is honest.
- Log incidents next to decisions. One incident restarts the count.
- Give the agent fewer tools. Least privilege made a small model worth reviewing.
The spoon only works when someone tastes with it. I still catch myself approving prompts without reading them, and the fix I trust is fewer prompts that matter more: fewer tools, a checkpoint on the risky calls, and a tally that lets the safe ones go and brings them back when the cook changes. The next post moves up to the Autonomous tier, where the senior cook plans tonight's special alone, within the budget and the rules.
Which permission prompt did you last approve without reading it? If the model behind your agent changed tomorrow, would its checkpoints come back on their own? And most importantly, who in your business decides how many clean decisions your riskiest tool has to earn?
Share this article
Enjoyed this article?
Subscribe to get more insights delivered to your inbox monthly
No spam, unsubscribe anytime.
This site is protected by reCAPTCHA and the Google Privacy Policy and Terms of Service apply.
Related articles
MCP Supply Chain Security: Rug Pulls, PII and Groundedness
MCP supply chain security on a laptop. Verify tool provenance, pin the tools/list hash against rug pulls, mask PII at the gateway and score groundedness.
AI Agent Guardrails: Tool Gate, Audit Log, Token Budget
AI agent guardrails with open source agentgateway: a per-role tool allowlist, audit log and token budget that stop a prompt injection, all run locally.
Sovereign Cloud Strategy: Residency Is Not Enough
Sovereign cloud vendors sell EU regions and sovereign SKUs, but the US CLOUD Act reaches data by possession, not location. Decide the real threat first.