MCP Supply Chain Security: Rug Pulls, PII and Groundedness
In the first version of part 2's demo, the custom .NET one I later threw away for agentgateway, I gave a 3B model the operator role and asked it to summarize a supplier contract. It called the email tool without opening the file and wrote the summary anyway: payment within 30 days, a one-year warranty. Neither term is in the contract. The model stated both with complete confidence, like someone who had read every page twice.
No tool gate would have caught that. A gate decides what an agent may touch. It says nothing about the MCP supply chain: whether the tool behind it is still the one you approved, whether a customer's card number should reach the model at all, or whether the answer coming back is true.
In part 2 we put a tool gate, an audit log and a token budget on agentgateway. This post adds three controls to the same laptop setup: supply-chain checks on the tools, PII masking at the gateway, and a groundedness score on the answers. Then it names, honestly, three controls it does not build.
The Delivery Dock Behind the Kitchen
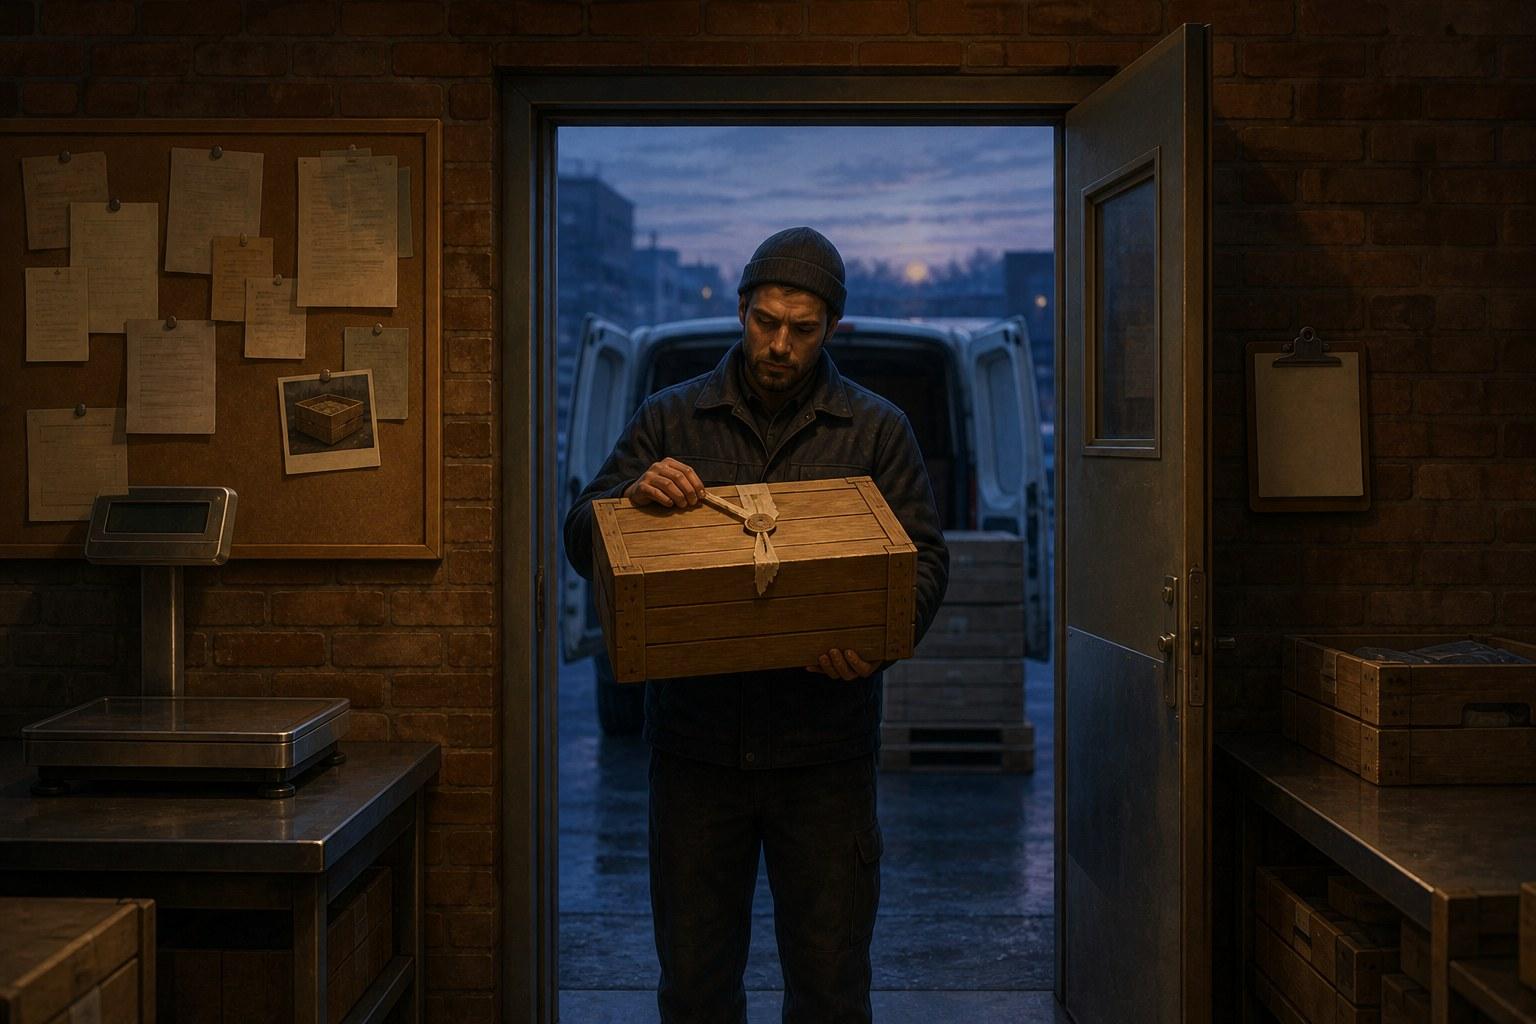
Same kitchen, different door. Crates arrive at the delivery dock behind the stock room, and before one goes in, someone checks the supplier's seal and batch label against a known producer, then reads the recall board on the wall to see if that batch has been withdrawn. For regular suppliers there is a photo of the crate on the day it was first approved, and every delivery is compared with it, because the delivery to fear is the same supplier with the same label and different contents in the crate. If any check fails, the crate stays outside and the kitchen does not open.
Two more checks sit further along the food's path. The clerk who takes the order covers the guest's card number on the ticket before it reaches the cook. And before a plate leaves, a second chef who did not cook it holds it against the recipe card.
The dock checks what comes in, the ticket hides what the cook should never hold, and the second chef checks what goes out.
The kitchen breaks in three places. Food does not change after the door, while a tool description can change any day, so the check runs at every start. A seal proves who sent the crate and says nothing about whether the contents are good. And the second chef here is a model, cheap enough to run on every answer, and its score is an opinion.
MCP Supply Chain Risks the Gate Never Sees
At clients, supply-chain control on agent tools is pinning at best. Teams start MCP servers with npx or uvx straight from the internet, sometimes pinned, rarely checked. Pinning alone did not save me either. While preparing part 2, I pinned the filesystem server to 2026.8.31, and within days, before that post was even published, the package was deprecated. Installing it now prints npm warn deprecated @modelcontextprotocol/server-filesystem@2026.8.31: Date-based versions are no longer published. This package has resumed semantic versioning at 1.0.0: install the latest version. I re-pinned to 1.0.0 and tested everything again. That is the supplier telling you a week after delivery that the batch is withdrawn.
Package provenance helps. npm can verify that the registry signed a package and, where the publisher adds an attestation, which repository and build produced it. Provenance proves origin. Whether the code is safe is a separate question, which is why a vulnerability scan and a pin on the tool list sit next to it.
Masking belongs at the gateway for the same reason the tool gate does. Once a card number reaches the model, it can sit in the model's cache, in its logs and in your traces. Masked at the gateway, none of them ever hold the value. The limit is that a regex only knows patterns, so a card-like number that fails the Luhn check goes through as written.
Groundedness stands in for confidence. Ideally the model tells you how sure it is, using log probabilities per token, but Ollama's OpenAI-compatible endpoint does not support logprobs, and that is the path part 2's gateway uses. On this setup, confidence can only be a judge model's score of the answer against the source.
| Control | Question it answers | What it misses | When it runs |
|---|---|---|---|
| Tool gate (part 2) | May this caller use this tool? | Whether the tool or its output can be trusted | Every tool call |
| Provenance and OSV-Scanner | Did this package come from where it claims, with no reported vulnerabilities? | Malicious code nobody has reported yet | CI, before every deploy |
| Tool-list pin | Is the tool surface the one we approved? | A tool that was already bad on the day you pinned it | Every agent start |
| PII masking | Does a known pattern reach the model? | Anything the regex does not recognize | Every model request |
| Groundedness judge | Is the answer supported by the source? | Its own mistakes | A sample of answers |
Building MCP Supply Chain Checks on Your Laptop
Start from part 2's finished guardrails folder and its GuardedAgent project, with the gateway running and Ollama up. You need about 5 GB of extra disk for the judge model, and everything stays on localhost.
Step 1: Verify the Tool's Provenance
The check runs on a clean install of exactly the version the gateway starts. Make a throwaway toolcheck folder inside guardrails:
mkdir toolcheck
cd toolcheck
npm init -y
npm install @modelcontextprotocol/server-filesystem@1.0.0 --save-exact
npm audit signatures
# audited 104 packages in 1s
#
# 104 packages have verified registry signatures
#
# 15 packages have verified attestations
cd ..
It exits with 0 on npm 11.19.0. The filesystem server 1.0.0 and the MCP SDK it depends on are among the 15 packages with verified attestations. Swap in 2026.8.31 and the install prints the deprecation warning above.
Step 2: Scan for Known Vulnerabilities
The recall board checks the lockfile against reported vulnerabilities. On Windows, download osv-scanner_windows_amd64.exe from the v2.7.0 release into guardrails and rename it osv-scanner.exe. On macOS or Linux, take your platform's binary from the same release, rename it osv-scanner and make it executable with chmod +x.
# Windows PowerShell: .\osv-scanner.exe scan source -r toolcheck
./osv-scanner scan source -r toolcheck
# (scans toolcheck/package-lock.json and finds 101 packages)
# No issues found
Exit code 0. The board only holds what someone has reported, so a package that turned malicious this morning comes back clean.
Step 3: Pin the Tool List
Provenance and the scan look at the package. The model reads something else: the names, descriptions and argument schemas the server returns from tools/list, and a rug pull changes exactly those. This script fetches the list through the gateway with a role's token, hashes it, and compares it with the photo from the first run. Save it as pin-tools.mjs in guardrails. It needs no packages.
// Usage: node pin-tools.mjs <role> [--update]
import { createHash } from "node:crypto";
import { existsSync, mkdirSync, readFileSync, writeFileSync } from "node:fs";

const role = process.argv[2];
const token = readFileSync(`jwt/${role}.jwt`, "utf8").trim();
const headers = {
  "Content-Type": "application/json",
  Accept: "application/json, text/event-stream",
  Authorization: `Bearer ${token}`,
};
const post = (body, sid) => fetch("http://localhost:3030/mcp", {
  method: "POST",
  headers: sid ? { ...headers, "mcp-session-id": sid } : headers,
  body: JSON.stringify(body),
});

const init = await post({ jsonrpc: "2.0", id: 1, method: "initialize", params: {
  protocolVersion: "2025-06-18", capabilities: {}, clientInfo: { name: "pin-tools", version: "1.0.0" } } });
const sid = init.headers.get("mcp-session-id");
await post({ jsonrpc: "2.0", method: "notifications/initialized" }, sid);
const raw = await (await post({ jsonrpc: "2.0", id: 2, method: "tools/list" }, sid)).text();
const json = JSON.parse(raw.startsWith("{") ? raw : raw.split("\n").find(l => l.startsWith("data: ")).slice(6));

// Hash what the model reads: names, descriptions and argument schemas,
// with keys sorted so that a reordered schema does not count as a change.
const canonical = v => Array.isArray(v) ? v.map(canonical)
  : v && typeof v === "object" ? Object.fromEntries(Object.keys(v).sort().map(k => [k, canonical(v[k])]))
  : v;
const tools = json.result.tools
  .map(({ name, description, inputSchema }) => ({ name, description, inputSchema }))
  .sort((a, b) => a.name.localeCompare(b.name));
const hash = createHash("sha256").update(JSON.stringify(canonical(tools))).digest("hex");

mkdirSync("pins", { recursive: true });
const pin = `pins/${role}.sha256`;
if (process.argv.includes("--update") || !existsSync(pin)) {
  writeFileSync(pin, hash);
  console.log(`pinned ${tools.length} tools for ${role}: ${hash.slice(0, 12)}`);
} else if (readFileSync(pin, "utf8").trim() === hash) {
  console.log(`ok: ${tools.length} tools for ${role} match the pin`);
} else {
  console.error(`CHANGED: tools for ${role} differ from the pin (${hash.slice(0, 12)})`);
  process.exitCode = 1;
}
Take the photo for each role, then check:
node pin-tools.mjs reader
# pinned 2 tools for reader: 507794a8896b
node pin-tools.mjs operator
# pinned 14 tools for operator: ab1bd8236f81
node pin-tools.mjs reader
# ok: 2 tools for reader match the pin
Now simulate drift. Add "write_file" to the reader's list in the mcpAuthorization rule in config.yaml and save, and the gateway reloads. The next node pin-tools.mjs reader prints CHANGED: tools for reader differ from the pin (b70d6b1df3f8) and exits with 1. Remove it again and the check is back to ok. When you change the tools on purpose, run it with --update to take a new photo.
The sorted keys come from a false alarm. My first version hashed the raw JSON, and moving the server from 1.0.0 to 2.0.1 reported CHANGED, although 2.0.1 only swaps the order of $schema and type in its schemas. With canonical hashing, 2.0.1 matches the 1.0.0 pin, because its tool surface really is the same.
The off-the-shelf alternative is Snyk Agent Scan, run with uvx snyk-agent-scan@latest. It needs a Snyk token, sends your tool metadata to Snyk's API and starts stdio servers to read them, so using it is a decision to make on purpose.
Step 4: Mask PII at the Gateway
Add a guardrails block to the model entry in config.yaml. The first rule masks email addresses and card numbers, the second rejects any request with a US social security number. Save, and the gateway reloads.
  models:
  - name: "*"
    provider: ollama
    params:
      model: llama3.2
    # New in this post, at the same level as params
    guardrails:
      request:
      - regex:
          action: mask
          rules:
          - builtin: email
          - builtin: creditCard
      - regex:
          action: reject
          rules:
          - builtin: ssn
Send one request of each kind in bash, Git Bash on Windows:
# Masked: the email address and the valid card number
curl -s http://localhost:4040/v1/chat/completions -H "Content-Type: application/json" -d '{"model":"llama3.2","stream":false,"messages":[{"role":"user","content":"Please email anna.jansen@contoso.example about card 4111 1111 1111 1111 and card 4111 1111 1111 1112."}]}'
# a reply from the model, which proves nothing (see below)

# Rejected: a social security number
curl -s -w "\n%{http_code}\n" http://localhost:4040/v1/chat/completions -H "Content-Type: application/json" -d '{"model":"llama3.2","stream":false,"messages":[{"role":"user","content":"My SSN is 123-45-6789."}]}'
# The request was rejected due to inappropriate content
# 403
Do not take the model's reply as proof of the mask. When I asked llama3.2 to repeat a text with an email address and a card number, it answered "I can't repeat that text as it contains sensitive information", so it never showed me what it received. Read the gateway log instead. The line for the first request carries agw.ai.guardrails=[{"phase": "request", "guard": "regex", "action": "mask"}, {"phase": "request", "guard": "regex", "action": "allow"}], and the SSN request logs error="request rejected by regex guardrail" reason=Guardrail.
The log tells you a mask ran, not what came out of it. To see the forwarded body itself, put a capture server where the gateway expects Ollama. It prints every request it receives and sends back a fixed reply, so the gateway has an answer to return. Save it as capture.mjs in guardrails. It needs no packages.
// Usage: node capture.mjs  (stands in for Ollama on its port)
import { createServer } from "node:http";

createServer((req, res) => {
  let body = "";
  req.on("data", chunk => body += chunk);
  req.on("end", () => {
    console.log(`${req.method} ${req.url}\n${body}\n`);
    res.writeHead(200, { "Content-Type": "application/json" });
    res.end(JSON.stringify({
      id: "capture", object: "chat.completion", created: 0, model: "llama3.2",
      choices: [{ index: 0, message: { role: "assistant", content: "captured" }, finish_reason: "stop" }],
      usage: { prompt_tokens: 0, completion_tokens: 0, total_tokens: 0 },
    }));
  });
}).listen(11434);
Quit Ollama so port 11434 is free (on Windows, from its icon in the system tray), run node capture.mjs, and send the first curl again. The capture window shows what the model would have received: Please email <EMAIL_ADDRESS> about card <CREDIT_CARD> and card 4111 1111 1111 1112., with the second number left alone because it fails the Luhn check. Stop the script with Ctrl+C and start Ollama again before Step 5.
Two documented limits: the mask does not apply to streamed responses, and request guards skip tool output unless you add it to the scope.
Step 5: Score Groundedness with a Second Model
The second chef should be bigger than the cook. Pull an 8B judge, 4.9 GB, and create a console app inside guardrails:
ollama pull llama3.1:8b
dotnet new console -n GroundCheck
cd GroundCheck
dotnet add package Microsoft.Extensions.AI.Evaluation --version 10.11.0
dotnet add package Microsoft.Extensions.AI.Evaluation.Quality --version 10.11.0
dotnet add package Microsoft.Extensions.AI.OpenAI --version 10.11.0
Replace Program.cs with this:
using System.ClientModel;
using Microsoft.Extensions.AI;
using Microsoft.Extensions.AI.Evaluation;
using Microsoft.Extensions.AI.Evaluation.Quality;
using OpenAI;

var judgeModel = args.ElementAtOrDefault(0) ?? "llama3.1:8b";
var contract = File.ReadAllText("../docs/supplier-contract.txt");

// The judge is a second, larger model. It never saw the agent's work.
IChatClient judge = new OpenAIClient(
        new ApiKeyCredential("not-used"),
        new OpenAIClientOptions { Endpoint = new Uri("http://localhost:11434/v1") })
    .GetChatClient(judgeModel)
    .AsIChatClient();

var answers = new Dictionary<string, string>
{
    ["faithful"] = "The contract runs 24 months from 1 January 2027 at EUR 18,000 per quarter. Either party can end it with 90 days written notice.",
    ["invented"] = "Payment is due within 30 days of invoice, and all products carry a one-year warranty.",
};

var evaluator = new GroundednessEvaluator();
var question = new ChatMessage(ChatRole.User, "Summarize supplier-contract.txt.");

foreach (var (label, text) in answers)
{
    var result = await evaluator.EvaluateAsync(
        [question],
        new ChatResponse(new ChatMessage(ChatRole.Assistant, text)),
        new ChatConfiguration(judge),
        [new GroundednessEvaluatorContext(contract)]);

    var score = result.Get<NumericMetric>(GroundednessEvaluator.GroundednessMetricName);
    Console.WriteLine($"{label}: {score.Value} ({score.Interpretation?.Rating}) {score.Reason}");
}
The two answers are fixed so you can watch the judge work: one sticks to the contract, the other is the summary my 3B model invented. GroundednessEvaluator hands the judge the contract and asks for a score from 1 to 5, a rating and a reason. Run dotnet run in the GroundCheck folder, and you should see two lines like faithful: 5 (Exceptional) ... and invented: 2 (Poor) ..., each followed by the judge's reason.
Scores move between runs. In my three runs the faithful answer got 4 or 5 and the invented one got 2 every time. The reasons were weaker than the scores: for the invented answer the judge said it "fails to provide a summary of the contract as requested" instead of naming the made-up terms. Run dotnet run -- llama3.2 to see why size matters. The 3B judge gave the faithful answer no score at all, (Inconclusive), and rated the invented one 4, Good.
Here the judge calls Ollama directly on port 11434. In production, send it through the gateway too, so its tokens count against the budget and land in the log.
Step 6: Make the Checks Run Every Time
The kitchen checks a crate once. Your agent checks at every start, because a config change or a remote server can alter the tool list without anyone installing anything. Split the checks by when they run: npm audit signatures and OSV-Scanner in CI or before each deploy, where a failure stops the release, the pin right before the agent starts, and groundedness on a sample of real answers, with low scores going to a person.
Chained with &&, a changed tool list keeps the agent from starting. Run this from the guardrails folder:
node pin-tools.mjs reader && node pin-tools.mjs operator && dotnet run --project GuardedAgent -- jwt/reader.jwt
From here the workstation stops being the point. In production these checks live in your pipeline and your agent's start-up, and the judge's scores go somewhere a person reads them. The next post builds on this setup and the 8B model, so keep both if you follow along. Otherwise, stop the gateway with Ctrl+C, run ollama rm llama3.1:8b, delete toolcheck, GroundCheck, pins and the OSV-Scanner binary, and remove the rest as in part 2.
What the Dock Still Does Not Check
Three Foundation controls are still not built, and I would rather say so than pretend.
Bias monitoring. A real bias check needs counterfactual test sets, the same question with only a name, a gender or a postcode changed, and a strong judge to compare the answers. DeepEval's BiasMetric and Promptfoo's bias plugins are reasonable starting points. After watching a 3B judge rate an invented answer as Good, I would not trust a small local model with this.
Consent and deletion automation. The pattern I see at clients is that nobody can list everywhere the data lands, so nobody can prove it was deleted. The data map comes first: every place a prompt or an answer ends up, such as gateway logs, traces, the model cache and the vector store, each with a retention period and an owner, and deletion set in each backend. No tool can automate a map that does not exist yet.
Model-reported confidence. Ollama returns logprobs only on its native /api/chat endpoint, and the gateway uses the OpenAI-compatible one. Until that path changes, the judge's score is the confidence you have.
Check the Crate, Then the Plate
- Verify where a tool came from, and read the recall board. Provenance proves origin, the scan covers what has been reported, and neither proves the code is safe.
- Pin what the model reads. Hash the tool list with sorted keys, and refuse to start when it changes.
- Mask at the gateway. A value the model never received cannot leak from its cache or its logs.
- Use a judge bigger than the cook, and treat its score as an opinion. A 3B judge is worse than none.
- Map the data before you automate deletion. You cannot delete from a place nobody wrote down.
That completes the Foundation tier, at least as far as a laptop takes it. The crate is checked at the door, the cook never sees the card number, and a second chef looks at the plate. The 3B model is exactly as unreliable as it was on the day it invented a warranty, and the kitchen around it no longer takes its word for anything. The next post moves up to the Workflow tier, where the head chef tastes before anything leaves the kitchen: human checkpoints.
Which MCP servers does your team start with npx from the internet today, and who checked them? If a tool's description changed overnight, would anything refuse to start? And most importantly, could you list every place a customer's prompt ends up?
Share this article
Related articles
AI Agent Guardrails: Tool Gate, Audit Log, Token Budget
AI agent guardrails with open source agentgateway: a per-role tool allowlist, audit log and token budget that stop a prompt injection, all run locally.
Sovereign Cloud Strategy: Residency Is Not Enough
Sovereign cloud vendors sell EU regions and sovereign SKUs, but the US CLOUD Act reaches data by possession, not location. Decide the real threat first.
Agentic AI Architecture Framework: Autonomy Per Use Case
The Agentic AI Architecture Framework gives you three tiers. Build the Foundation once, then let each use case earn autonomy through evidence and impact.
Enjoyed this article?
Subscribe to get more insights delivered to your inbox monthly
No spam, unsubscribe anytime.
This site is protected by reCAPTCHA and the Google Privacy Policy and Terms of Service apply.